The Average That Lied
We were reviewing a D2C brand's Meta ad account with them recently when we ran into something worth writing up properly, because the short version (which we posted on LinkedIn) leaves out most of the mechanism.
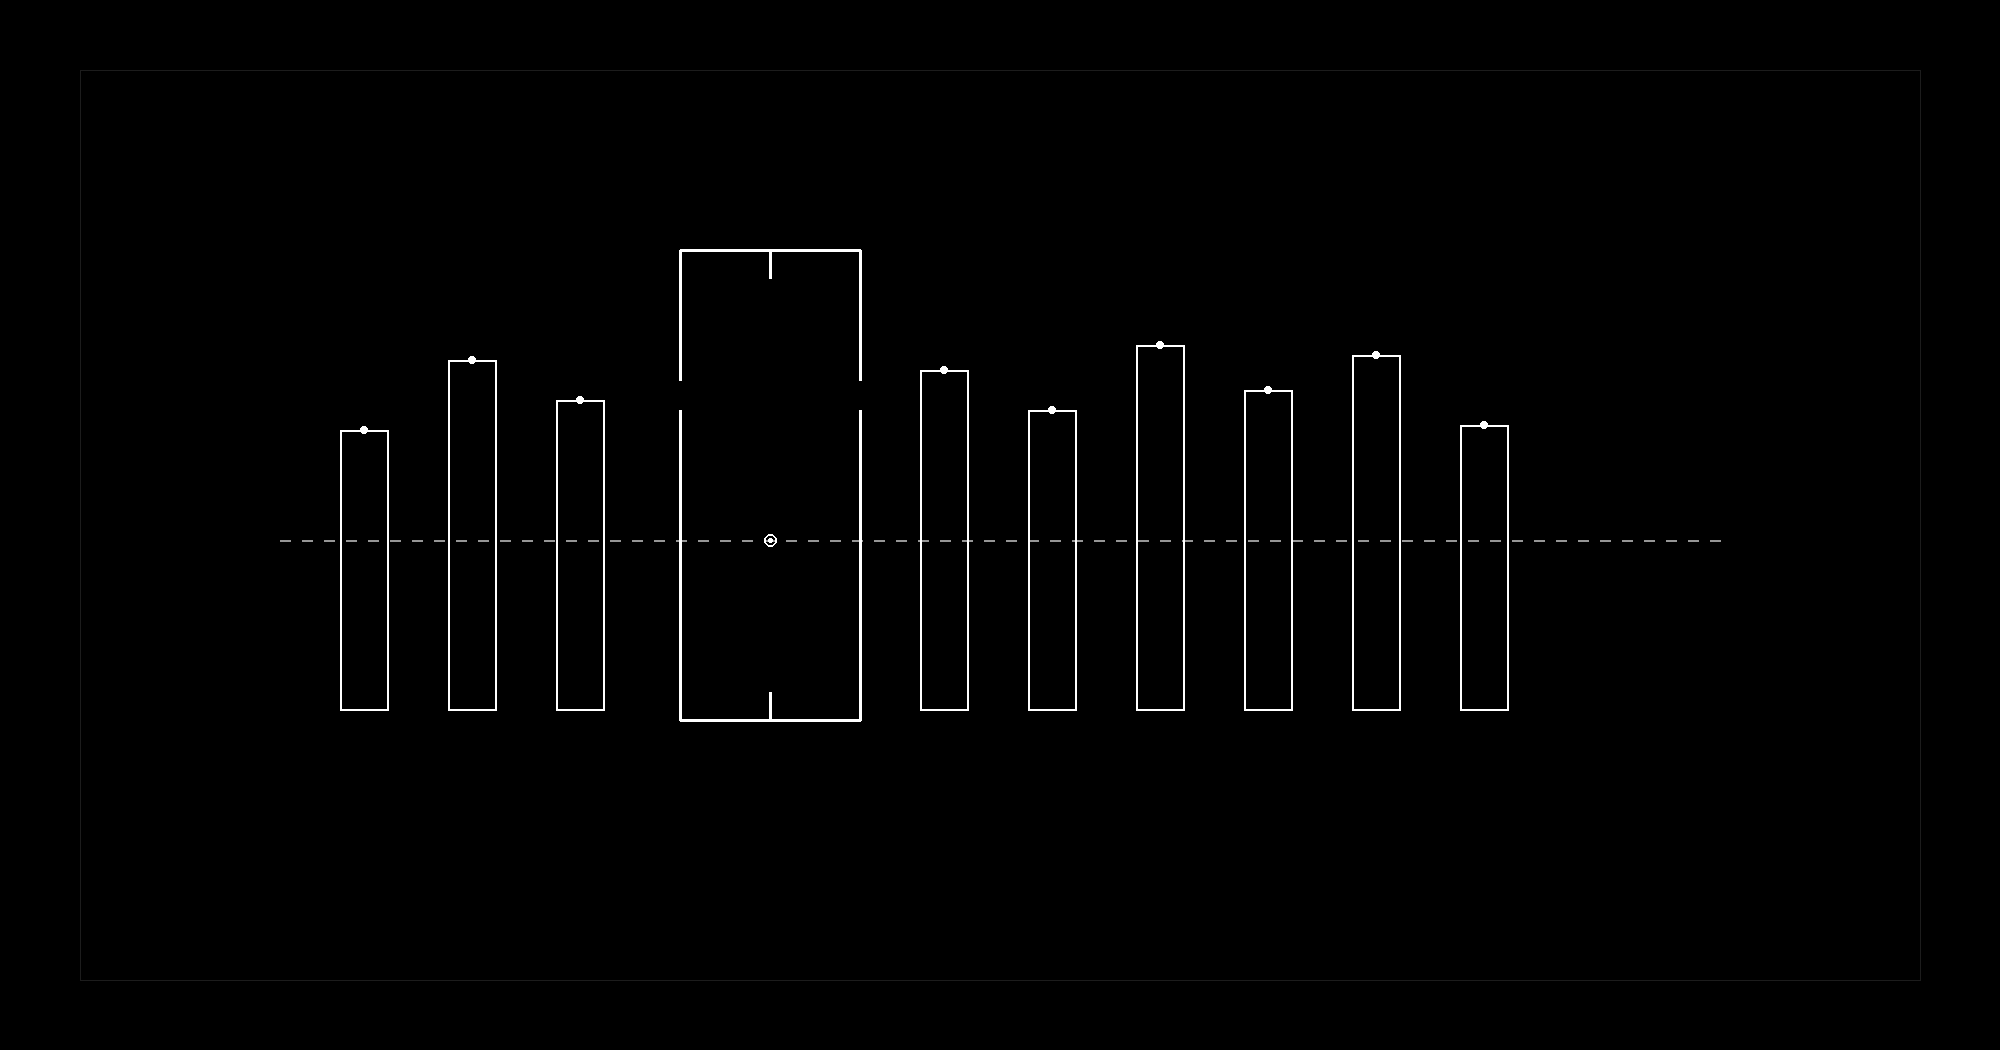
Here's the short version first. Inside one ad set, a single ad was carrying 49% of that ad set's entire budget, running at 1.94x ROAS — well under what anyone would call viable. But the ad set's own reported number, the blended ROAS averaged across every ad inside it, read 3.34x. That's close enough to its 3.50x target, and close enough to its peer group, that the standard read on this account was: leave it alone.
We pulled the ad set apart, ad by ad, and recomputed the same calibration and uplift math on what was left after removing that one ad. The surviving ads cleared the viability floor with room to spare and landed at 3.82x — above target. The exact same ad set, same spend everywhere else, scored "hold" as a whole and "scale" once you separated out the one ad quietly eating the average.
That's the headline. The mechanism underneath it is more interesting, and it's the part that got cut from the short version.
Why the average hides this
Meta allocates budget at the ad-set level. It has no concept of per-ad budget — you can pause an individual ad, but you cannot give it a smaller or larger slice of spend directly. So every reporting and decisioning system that operates on Meta data is, by construction, built around the ad set as the unit of budget. The ad set's ROAS is a blended number, a mean across every ad running inside it.
A mean is a lossy statistic whenever what's underneath it isn't one population. Ten ads with meaningfully different creative, different funnel intent, different fatigue states, and wildly different returns get compressed into a single number. If nine of those ads are healthy and one is a large, quiet failure, the mean can still land inside a perfectly reasonable-looking range. Nothing about the number itself signals that it's hiding a bimodal distribution. You'd need to go looking for it.
Most tools don't go looking for it, because the budget lever operates at the ad-set level too. If the ad set's blended ROAS says "fine," the natural conclusion is that the ad set's budget is fine as it is. But the ad set's budget was never the problem here. The problem was how that budget was distributed across ten different ads — and no amount of turning the ad-set-level dial up or down would have fixed that.
The two things that made this easy to miss
Two more details made this particular case harder to catch than it should have been.
First, the peer group this account was being benchmarked against was itself mostly unhealthy. When we checked the comparison cohort, the majority of accounts in it were below their own individual viability floors. "In line with the peer median" sounded like a clean bill of health, but it actually meant "in line with a group that's mostly failing." A benchmark built from a failing cohort doesn't tell you anything useful — it just launders the bad number through a comparison that looks rigorous.
Second, part of the account's reported return was coming from indirect channels — marketplace halo, cross-channel attribution — rather than directly from the ads being judged. That indirect credit was propping up the blended number just enough to keep it above the kill floor on a basis that included it, even though the directly attributed return was running under that same floor on its own. Two numbers that should have been kept separate — what the ads themselves earned, and what got credited to them from elsewhere — were getting mixed together at exactly the point where a real problem should have been visible.
Stack those two things on top of the ad-level concentration problem, and you get an account that clears every check a normal review would run: reasonable blended ROAS, in line with peers, positive contribution from cross-channel effects. Every individual signal reads fine. The thing that was actually wrong — one ad eating half the budget at under 2x — never shows up in any of them, because none of them were built to isolate it.
What actually fixed it
The fix wasn't a bigger or smaller budget on the ad set. It was decomposing the ad set down to the individual ad, finding the one responsible for the concentration, and recomputing the same math on what remained after removing it. That's a different kind of check than "is this number in a healthy range" — it's closer to asking "does this number survive being taken apart."
In practice, that means: for any container-level metric (ad set, campaign, SKU category, whatever the unit happens to be), check what fraction of the underlying spend is sitting below the container's own floor, and check whether removing the worst offender flips the read. If it does, the story isn't a budget problem at the container level at all. It's a composition problem — one part of the container is quietly wrong, and the container's average is doing exactly what averages do: hiding it.
This is the kind of blind spot our decision intelligence platform, Niti, is built to catch — not by producing a bigger dashboard, but by making sure the numbers that decide something get checked at the grain where the problem actually lives, not just the grain where the budget lever happens to sit.
If your best-looking accounts are sitting on "hold," it's worth pulling the average apart before touching the budget at all.